Web Hosting and SEO

How Web Hosting Affects Technical SEO and AI Search

A practical guide to server response, rendering, CDNs, cloud platforms, log file analysis, and crawler access across search and AI systems.
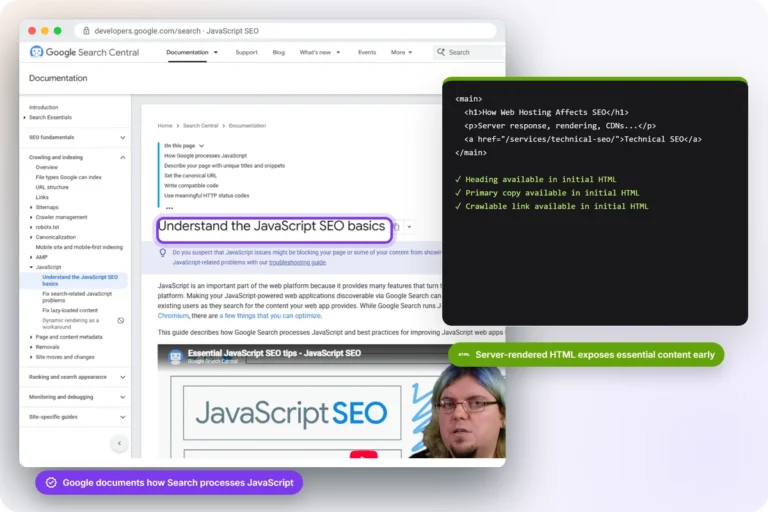
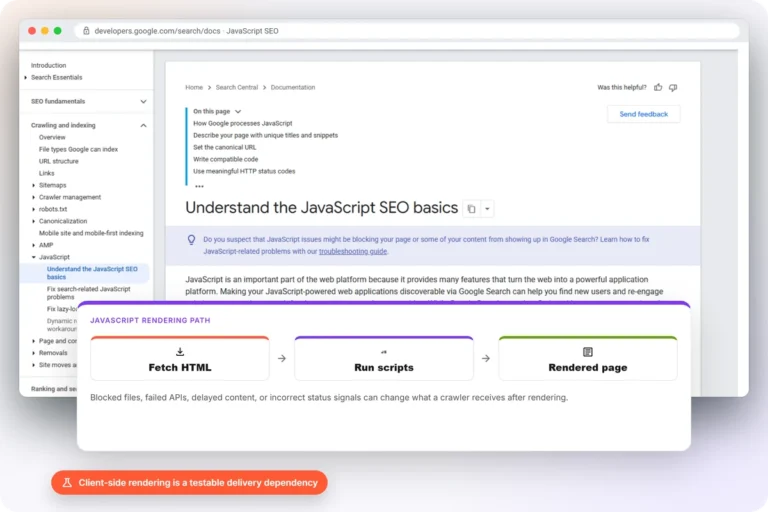
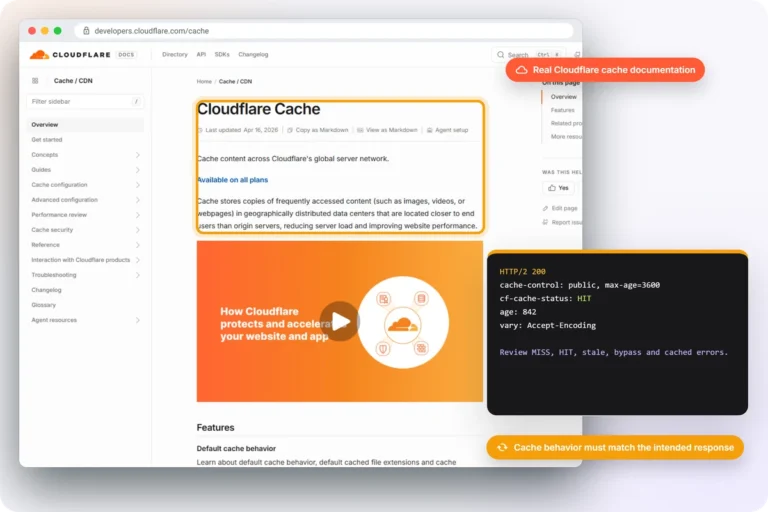
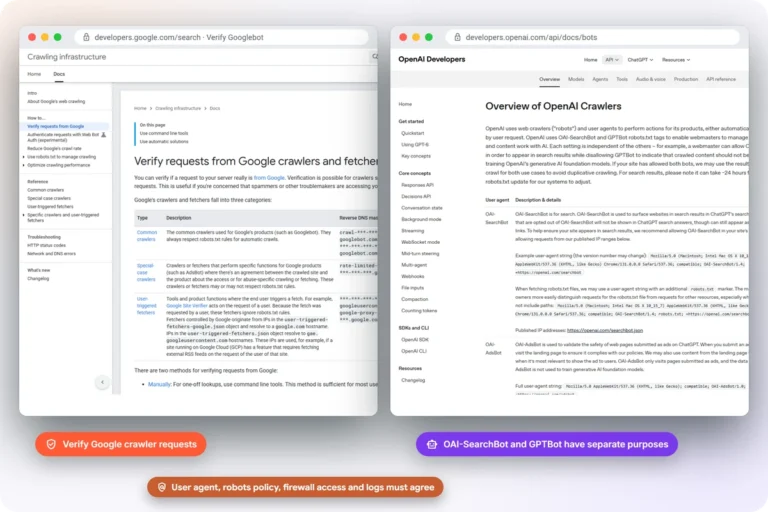
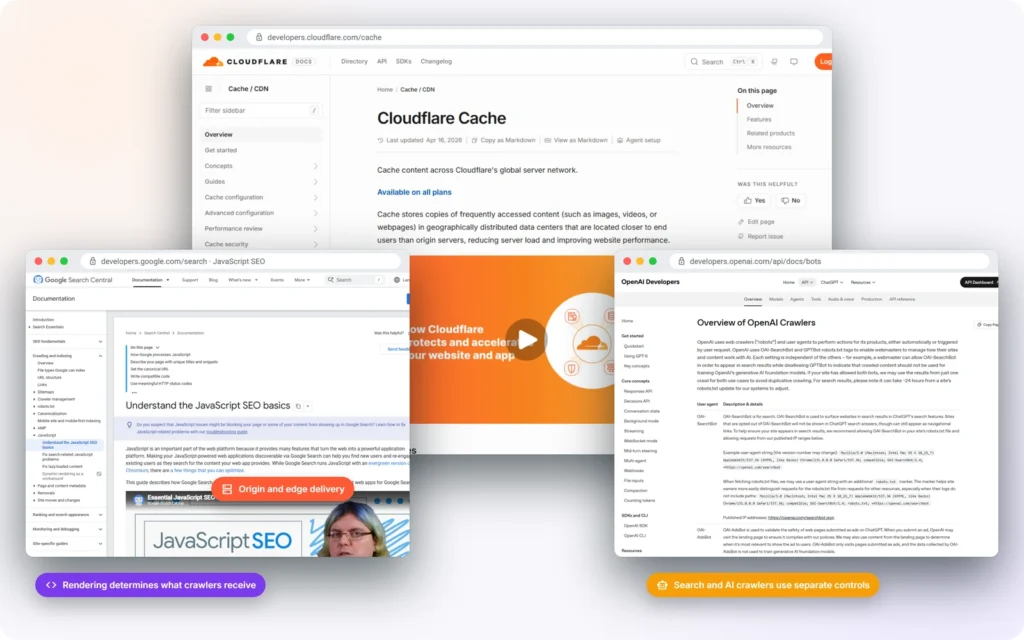
The web hosting page layered with Google JavaScript SEO documentation and Cloudflare cache documentation to show how the origin, rendering and edge delivery affect crawler access
On this page
    Add a header to begin generating the table of contents
    Scroll to Top

    Hosting Infrastructure Can Help or Hurt Search Visibility

    Web hosting affects technical SEO when infrastructure changes what people and crawlers can reach, how quickly the origin responds, and whether a page arrives with its important content intact. A strong platform cannot make an irrelevant page rank, but recurring timeouts, DNS failures, 5xx errors, blocked bots, stale caches, or incomplete JavaScript rendering can limit crawling and indexing before content quality is evaluated.

    The hosting company is only one layer. The application, database, rendering method, CDN, firewall, cache rules, deployment process, and third-party scripts all influence the final response. The useful question is not which host is best in general. It is whether the full delivery stack is reliable for the site’s traffic, content model, security requirements, and release cadence.

    Search engines and AI products also differ. Some render JavaScript; others depend more on initial HTML. Search, answer, and training bots may use separate user agents and controls. Test the systems that matter using logs and rendered-page evidence rather than one universal rule.

    What's included

    Server Performance, Rendering, and Crawler Access

    Search visibility depends on what the origin, application, CDN, and security layer deliver to each request.
    How it works

    Log File Analysis Shows How Crawlers Use the Site

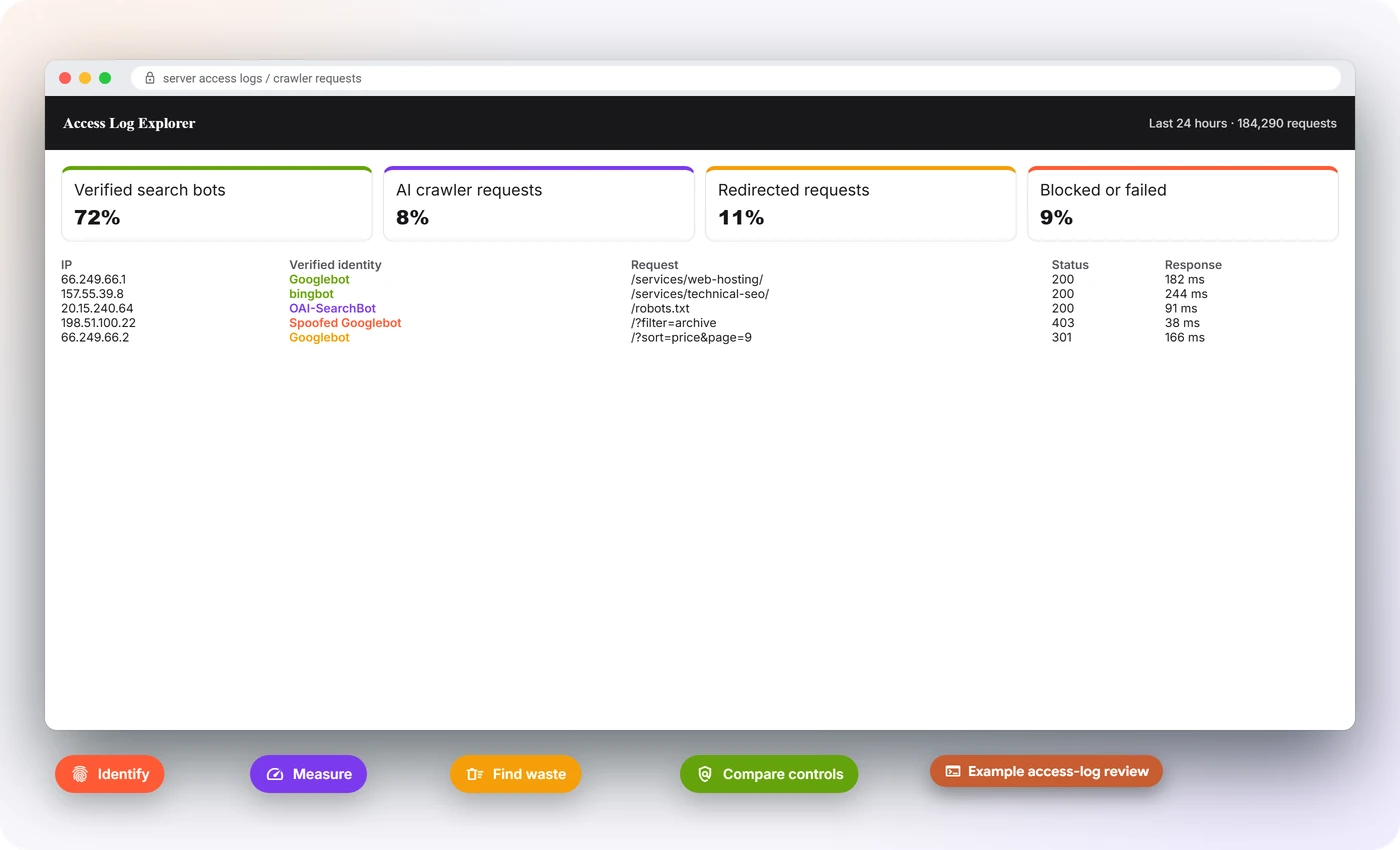
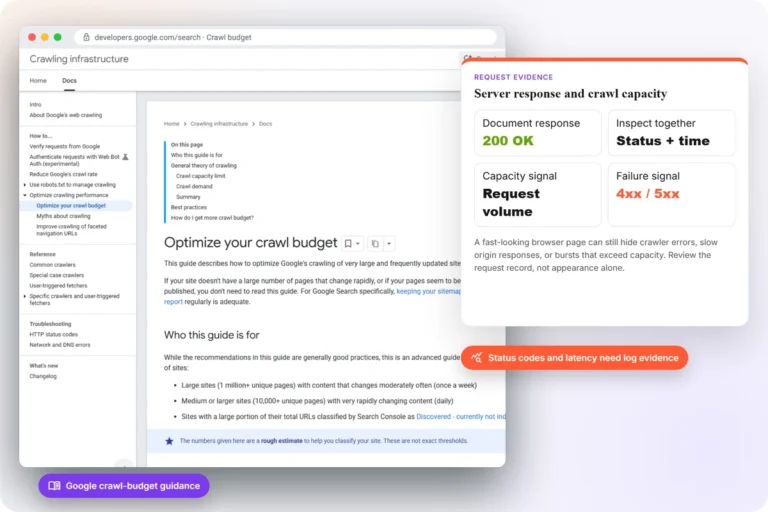
    Example server access log analysis identifying verified Googlebot, Bingbot and OAI-SearchBot requests alongside redirects, blocked bots, response codes and latency
    Step 1 · Identify

    Search and AI Bot Verification

    Separate verified Googlebot, Bingbot, and named AI user agents from spoofed or generic bot traffic.
    Step 2 · Measure

    Crawl Rate and Server Responses

    Measure request frequency, response time, status codes, and spikes that can reveal capacity or access problems.
    Step 3 · Find Waste

    Crawl Budget and URL Waste

    Find repeated requests to parameters, redirects, duplicate URLs, errors, and low-value pages. Crawl budget matters most on large or frequently changing sites.
    Step 4 · Control

    Robots.txt and Bot Controls

    Compare directives with actual requests. Robots.txt guides compliant crawlers; firewall and authentication rules enforce access.
    Engagement options

    Hosting Options by Site Complexity

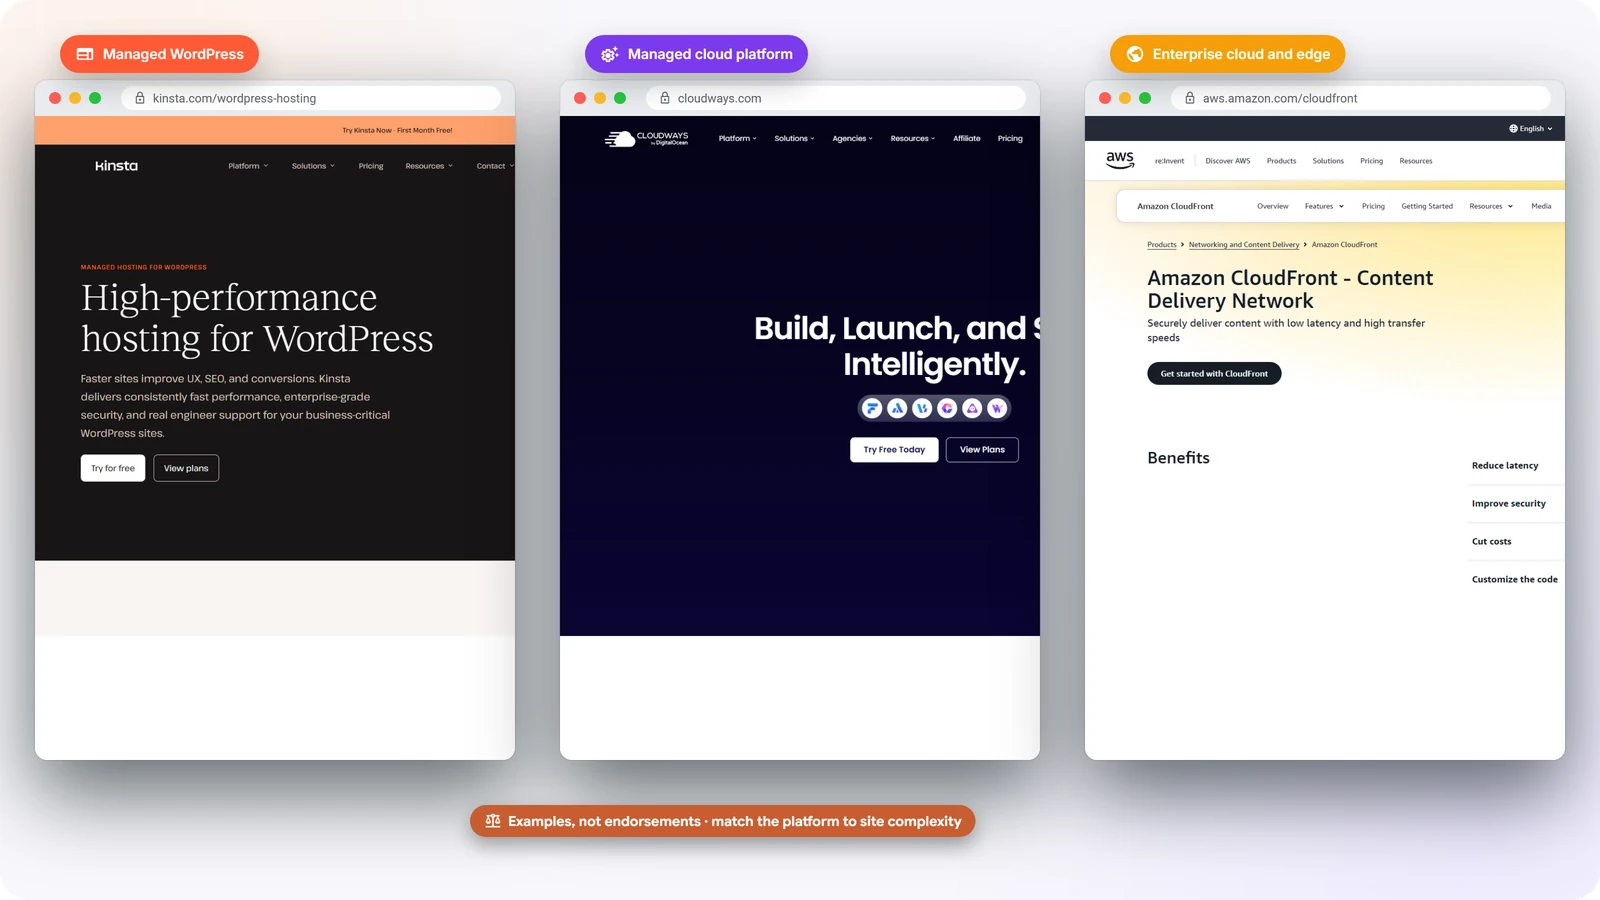
    Provider names are examples, not endorsements. The right fit depends on traffic, application complexity, team capacity, security, and support requirements.
    Real Kinsta, Cloudways and Amazon CloudFront pages representing managed WordPress hosting, managed cloud platforms and enterprise cloud and edge infrastructure

    Managed Hosting

    A practical fit for many WordPress and smaller business sites that need platform-managed operations.
    Most common

    Managed Cloud Platforms

    Useful for growing sites that need more infrastructure control without owning every operational task.

    Enterprise Cloud and Edge

    Suited to complex applications, global traffic, and strict security or deployment requirements.
    FAQ

    Web Hosting and Technical SEO Questions

    Changing hosts can improve reliability, response time, or delivery control, but it does not create relevance or authority. A migration can also cause temporary crawl changes or larger problems when DNS, redirects, certificates, firewall rules, or status codes are misconfigured.
    Server-side or static rendering often makes important content available in the initial HTML and reduces dependence on JavaScript execution. Client-side rendering can still work when crawlers can access the scripts, links, content, and correct status signals. The right choice depends on the application and the crawlers that need access.
    Yes. Bot rules, rate limits, challenges, IP restrictions, robots directives, and cached error responses can block or distort access. Search crawlers and AI bots should be evaluated separately because they use different user agents and may serve different purposes.

    Related Technical SEO Topics

    Scroll to Top